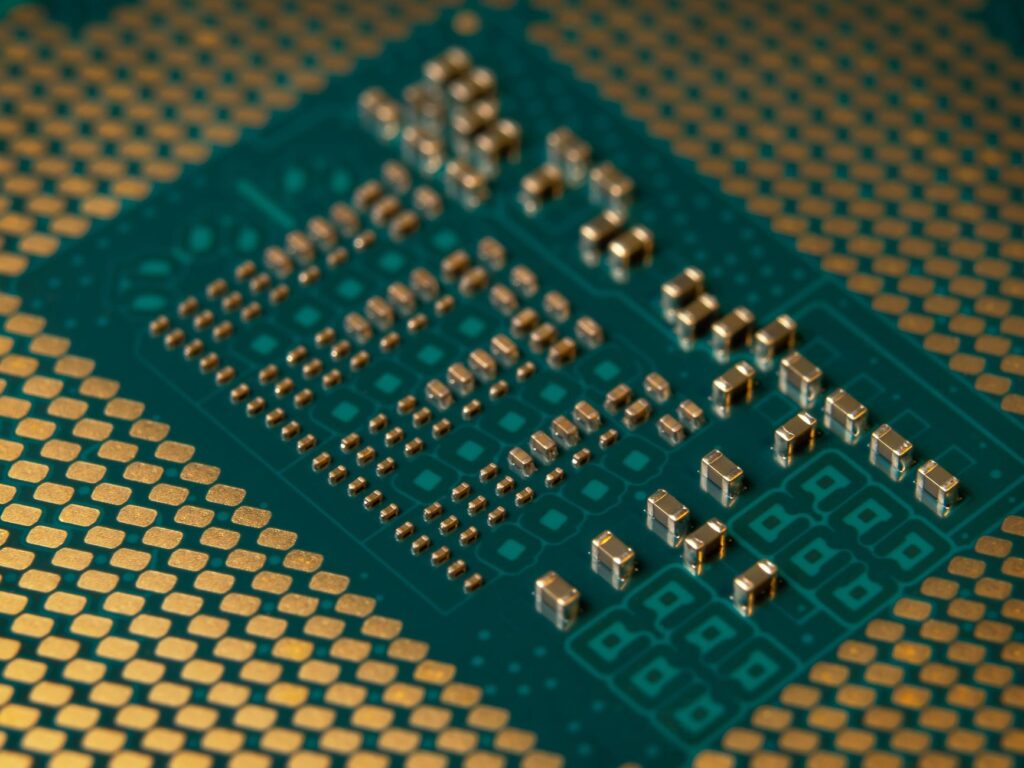
Imagine a chip that clears every test on the production floor, ships by the million and then starts failing inside customers' products six months later. Nothing looked wrong on the dashboard. The pass rate was healthy, the yield was strong, and the test program ran on schedule. Yet something slipped through.
Table Of Content
- Why Coverage Is More Than a Percentage
- Fault Coverage and Test Coverage
- Defect Level and DPPM
- Memory, Mixed-Signal and System-Level Coverage
- Functional and Verification Coverage
- Parametric Margins and Process Capability
- Test Time, Cost and Yield
- Correlation and Escape Tracking
- Building a Practical Coverage Dashboard
- Conclusion
This is the quiet risk behind semiconductor testing: a high pass rate only tells you the chips passed the tests you wrote, not whether those tests were good enough. Coverage metrics fill that gap. They reveal what your tests actually check, what they miss, and how much risk remains. Here are the key metrics every engineering team should track.
Why Coverage Is More Than a Percentage
A coverage number is only meaningful when you know what it measures. A figure of 99% might sound reassuring, but it can describe stuck-at faults on digital logic, while leaving timing paths, memories, analog blocks, and real-world operating conditions less thoroughly examined.
The most effective teams track several kinds of coverage together, then connect them to outcomes such as defect rates, yield, and field returns. The goal isn't to chase a single impressive number, but to understand where risk sits and how it changes as designs grow more complex.
Fault Coverage and Test Coverage
Fault coverage is the share of modeled faults that your tests can detect. Digital teams typically track several fault models:
- Stuck-at faults: nodes stuck at logic 0 or 1, the classic baseline.
- Transition and path delay faults: failures in switching speed, increasingly important at advanced nodes and high frequencies.
- Bridging and cell-aware faults: shorts between nets and defects inside standard cells.
Test coverage measures testable logic exercised, revealing remaining gaps by fault model, block, and time while supporting application-specific quality targets.
Defect Level and DPPM
Coverage becomes meaningful when you translate it into customer impact. The Williams-Brown model offers a useful, if simplified, relationship: defect level equals one minus yield raised to the power of one minus fault coverage. Take a process with 90% yield. At 99% coverage, the model predicts roughly 1,050 defective parts per million (DPPM) reaching customers.
Raise coverage to 99.9%, and that drops to around 105 DPPM. A 0.9-point improvement in coverage cuts escapes by about a factor of ten. Real-world numbers differ because faults aren't uniform, but the lesson holds: small coverage gains can have outsized effects on quality, especially for automotive, medical, and industrial products where targets can be in the low single digits of DPPM.
Memory, Mixed-Signal and System-Level Coverage
Modern chips are rarely just logic. Embedded memories can occupy much of a die, analog blocks handle power and signals, and high-speed interfaces add their own challenges. Effective IC testing therefore tracks coverage beyond digital logic:
- Memory coverage: built-in self-test algorithms and repair strategies, measured by the fault types they detect and the percentage of bits covered.
- Analog and mixed-signal coverage: the share of specifications, corners, and operating modes verified against limits.
- Interface and I/O coverage: high-speed links, protocols, and power states.
- System-level test coverage: real-world workloads that catch interaction problems structural tests miss.
These categories are harder to quantify than digital faults, but ignoring them leaves blind spots exactly where complex systems-on-chip are most vulnerable.
Functional and Verification Coverage
Testing doesn't start on the tester. Pre-silicon verification generates its own coverage data, including code coverage (lines, branches, toggles, and state machines) and functional coverage (whether specified features and scenarios have actually been exercised). Teams should link these metrics to post-silicon findings. If a bug appears in silicon in an area with thin verification coverage, that is a signal to strengthen the process, not just fix the chip.
Parametric Margins and Process Capability
Passing a limit isn't the same as passing with margin. Parametric coverage looks at how close measurements come to specification limits across voltage, temperature, and process corners. Process capability indices such as Cpk quantify how comfortably a distribution sits within limits. A test with a falling Cpk may signal drift in the process or tester long before yield drops, giving engineers time to respond.
Test Time, Cost and Yield
Better coverage often means more test time, and test time is money. Track:
- Test time per device and throughput on each tester.
- Cost of test per unit, including handlers, probe cards, and tester time.
- First-pass yield and retest rates.
- Coverage per second of test time, which highlights inefficient tests.
This lets teams make informed trade-offs, such as using scan compression to raise coverage without a matching increase in test time, or removing redundant tests that add cost without adding detection.
Correlation and Escape Tracking
The ultimate check on any test program is what happens afterward. Teams should monitor:
- Correlation between wafer-level, final test, system-level test, and bench measurements.
- Customer returns and field failures, analyzed by root cause.
- Escapes: defects that reached customers because no test detected them.
- Measurement repeatability, often assessed through gauge repeatability and reproducibility studies.
Every escape is a lesson. Feeding failure analysis findings back into test development closes the loop and steadily improves coverage where it matters most.
Building a Practical Coverage Dashboard
A useful dashboard brings these metrics together without overwhelming the team:
- Coverage by fault model, block, and test insertion.
- Estimated defect level and measured DPPM.
- Parametric margins and Cpk trends.
- Test time, cost, and yield.
- Correlation status and open escape investigations.
Review it regularly, and tie every metric to a decision, such as adding tests, removing redundancy, or updating limits.
Conclusion
Strong test coverage isn't a single percentage. It's a set of connected metrics covering fault detection, defect levels, memory and analog behavior, verification quality, margins, cost, and real-world correlation. Tracking them together exposes hidden risk and shows where each test hour delivers the most value. This discipline starts before silicon exists, so teams working on designing embedded system products should plan test strategy and coverage targets alongside architecture, not after it. The earlier coverage is measured, the cheaper and faster quality becomes.
Tessolve is an end-to-end silicon and systems engineering partner with more than 4,000 employees across 12 countries and over 22 years of experience. They support more than 90% of the world's top 20 semiconductor companies, using advanced labs and test expertise to help customers move chips from design to production.